SnapOtter
- Platform
- Docker Self-hosted
- Licence
- AGPL-3.0 Open source
- Website
- snapotter.com
- Source code
- github.com/snapotter-hq/SnapOtter
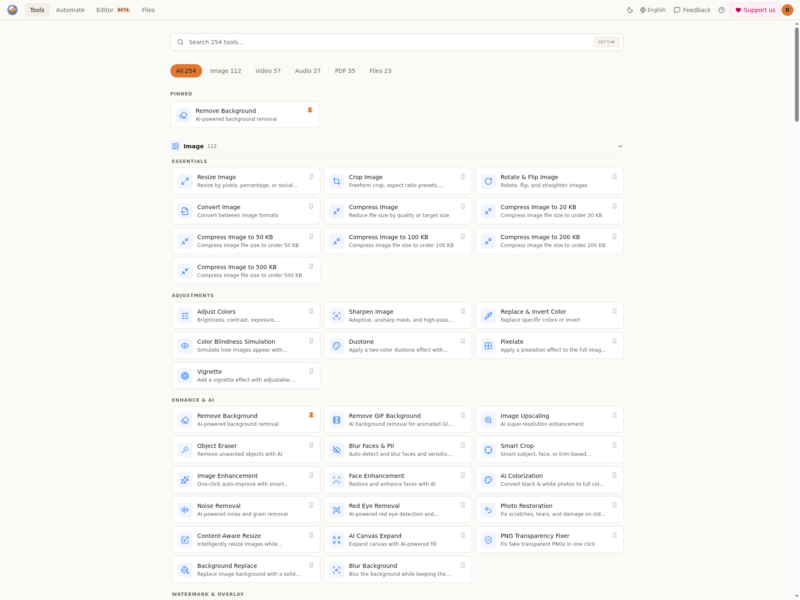
SnapOtter is a self-hosted file-processing suite: 200-plus small utilities behind one web interface, a REST API and a pipeline engine. It covers five modalities – images, video, audio, PDFs and structured data files – so conversion, compression, OCR, transcription, metadata stripping and local AI cleanup all run on your own hardware. Nothing is uploaded to a third party, which makes it a realistic replacement for CloudConvert, Smallpdf, TinyPNG and Otter.ai on a homelab or inside a company that cannot send customer documents to an outside service.
What is in the box
- Image tools (112) – resize, crop, compress, convert, watermark, colour adjustments, screenshot beautifying, vectorise, GIF handling, duplicate finder, passport photos, plus dedicated converters (JPG to PNG, HEIC to JPG, WebP to PNG, image to PDF). Accepts 55+ input formats including 23 camera RAW formats, writes 17 output formats.
- Video tools (57) – convert, compress, trim, resize, crop, merge, video to GIF, extract audio, stabilise, change frame rate, burn or extract subtitles, plus format-specific converters such as MOV to MP4, MKV to MP4 and MP4 to MP3.
- Audio tools (27) – convert, trim, normalise, change volume, fade, pitch shift, silence removal, noise reduction, merge and split, waveform rendering, plus M4A to MP3, AAC to MP3, OGG to WAV and similar.
- PDF tools (35) – merge, split, compress, convert, protect and unlock, redact, sign, watermark, page numbering, a multi-tool page editor, OCR and PDF to JPG/PNG/TIFF export.
- Data and archive tools (23) – CSV, JSON, XML and YAML conversion, CSV merge and split, Excel to CSV, a chart maker, and ZIP creation and extraction.
Local AI
A second layer runs models on your own machine: background removal, image upscaling, photo restoration and colourisation, object erasing, face blurring and enhancement, OCR from images and PDFs, audio transcription, automatic video subtitles, canvas expansion and transparency repair. The bundled fast OCR engine adds roughly 25 MiB to the image, and an accuracy pack can be installed on demand. An NVIDIA CUDA Compose file accelerates background removal, upscaling and transcription; Intel and AMD integrated graphics are not used for AI inference, so those hosts fall back to CPU.
Browsers, pipelines and API
The built-in image editor is layer-based with brushes, shapes, adjustments, filters, curves and keyboard shortcuts. Pipelines chain tools into reusable workflows – 20 steps by default, configurable through MAX_PIPELINE_STEPS, importable and exportable as JSON – and batch size is unlimited in the published image, 100 in a source build. Every tool is also reachable over a REST API with API-key authentication and interactive documentation at /api/docs, so the same operations can be scripted or wired into an existing workflow engine.
Deployment
A single docker run starts the whole stack with an embedded PostgreSQL 17 and Redis 8 on port 1349; the production path is a three-container Compose stack with the same services separated. The first login uses admin / admin and forces a password change. Images are published for AMD64 and ARM64, so it runs on an Intel box, Apple Silicon or a Raspberry Pi, and the interface is translated into 21 languages with right-to-left support for Arabic. OIDC and SSO are supported, so it can sit behind Google, GitHub, Okta or any OpenID Connect provider.
Things worth knowing
Basic analytics are enabled by default to help the maintainers find bugs; they can be turned off at build time with SNAPOTTER_ANALYTICS=off or at runtime from the admin settings. The suite is broad rather than deep – dedicated single-purpose utilities still win on edge cases – and the heavier AI filters are noticeably slower without a GPU. For pure PDF work, Stirling PDF is a lighter tool; for image compression, Squoosh; and anything scripted can go straight to FFmpeg, which SnapOtter itself drives.