I, Librarian
- Platform
- Web Docker Linux Windows
- Licence
- GPL-3.0 Open source
- Website
- i-librarian.net
- Source code
- github.com/mkucej/i-librarian-free
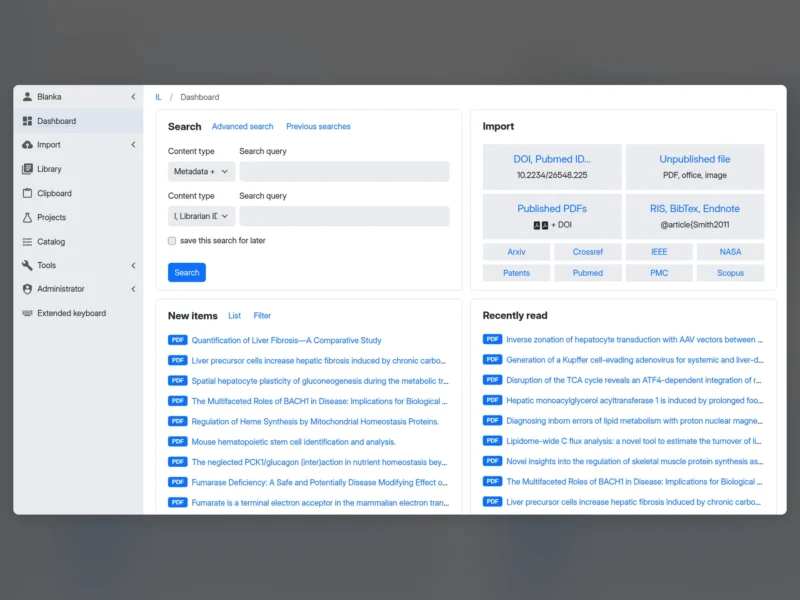
Overview
I, Librarian is a web-based PDF organiser for a research library. Instead of a folder tree of renamed files, it keeps one database of papers with their bibliographic metadata, so a few thousand PDFs stay searchable, taggable and citable rather than scattered across directories. It runs in a browser, at home on a laptop or on a departmental server, and the free edition covered here is the open-source version of the developer’s commercial product.
Getting metadata in without typing it
Records can be imported from Crossref, PubMed, arXiv, IEEE, NASA and patent repositories, so a paper’s authors, journal, DOI and year arrive with the file instead of being retyped. Optional LibreOffice and Tesseract integrations extend the same pipeline to Office documents and to OCR of scanned PDFs.
Finding things again
- Boolean search across the library’s metadata and full text, the usual way to narrow a systematic review down to the papers that matter.
- Tags and collections — bulk tagging, collection management and export, applied to a selection rather than one record at a time.
- Built-in PDF viewer — read a paper in the browser, with annotation tools, instead of downloading it again.
- No sync layer — one database on one server is the single source of truth, so there is no second copy of the library to reconcile between devices.
- Multi-user groupware — accounts and shared libraries for a research group, with an administrator area for software checks and global settings.
Running it
The free edition installs on the usual LAMP stack: Apache 2.4 or Nginx with PHP 8, a database, and the application files under the web root. Release installers exist for Windows, plus a DEB package and a console installer for Debian and Ubuntu, and both of those configure Apache and PHP for you. A Docker route is documented as well — build the image from the release tarball, mount a data directory and a config directory, and the container serves the library on port 80 (the documented example publishes it on 127.0.0.1:9050). The data directory has to be writable by UID/GID 33.
The application is PHP, and the free edition trails the hosted product: the AI summarisation and document-set querying on the vendor’s site belong to the commercial version, not to the open-source code.
Alternatives
For a reference manager that runs as a desktop application rather than a server, Zotero remains the standard; a document server such as Paperless-ngx handles scanned paperwork rather than papers. I, Librarian sits between them: a self-hosted, browser-based library built specifically around PDFs and their citations.