ArchiveBox
- Platform
- Docker Linux Windows macOS
- Licence
- MIT Open source
- Website
- archivebox.io
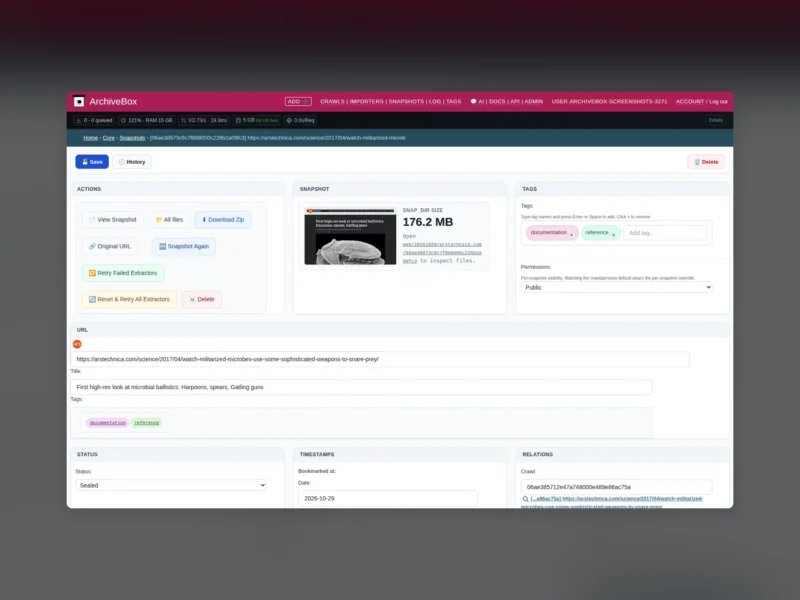
ArchiveBox is a powerful, self-hosted web archiving platform that lets you save snapshots of web pages, bookmarks, browser history, and feeds for offline viewing and long-term preservation. It ingests URLs from multiple sources and stores each page as a browsable, timestamped archive — including the HTML, PDF, screenshots, and extracted text. Designed for individuals, researchers, and organisations that want to own a permanent record of content that may vanish from the live web.
Key Features
- Multi-format snapshots — Stores each page as HTML, a PDF, a full-page screenshot, extracted text, and more in a single archive entry.
- Broad ingestion sources — Imports URLs from bookmarks, browser history, RSS feeds, Pocket/Pinboard lists, and the command line.
- Self-hosted & portable — Everything runs on your own server; the entire archive is stored as files on disk, fully under your control.
- CLI & web UI — Drive it from the terminal or browse and search your archive through a built-in web interface.
- Scheduled & repeat archiving — Re-save pages to capture changes over time and monitor disappearing content.
- Standards-based output — Exports standard web and PDF files that remain readable and forward-compatible for decades.
Why Use ArchiveBox?
The web changes constantly — pages get edited, paywalled, or taken down entirely. ArchiveBox gives you a personal, permanent snapshot of the content you care about, without relying on third-party services. Because it is open source and self-hosted, your archive is never subject to a vendor’s shutdown or terms of service.
Use Cases
- Preserving articles, blog posts, and references for research and citation
- Safeguarding business, legal, or compliance documents before they disappear
- Keeping a browsable offline copy of bookmarks and reading lists
- Monitoring sites for content changes or takedowns over time